ioGallery: Every Asset in One View, Understood by AI
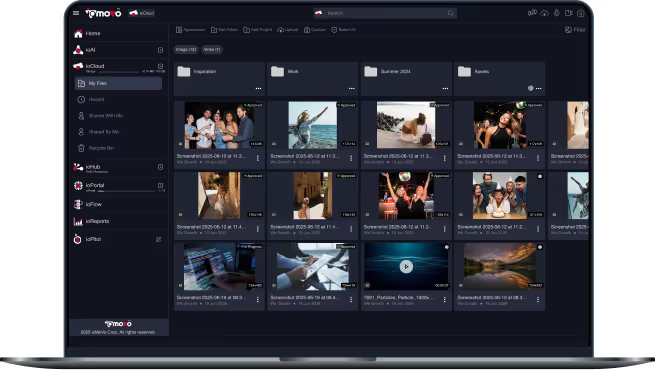
ioGallery gives your team one visual view of every file across ioCloud and connected drives. Behind it, ioMoVo's AI extracts meaning, generates metadata and powers intelligent workflows across ingestion, tagging, transcription, compliance and delivery, on the models you choose: commercial LLMs, open source models, vision and multimodal models, or sovereign deployment on your own GPUs. MCP enabled. A2A coordinated.

BYO-AI architecture
On premise GPUs
MCP integration
Sovereign deployments
RAG-controlled boundary
Why Teams Choose ioGallery
Model-agnostic
Commercial, open-source, vision/multimodal, sovereign — your choice, your infrastructure
Production-grade
Auto-tagging, transcription, OCR, semantic search, RAG, AI agents — today, not roadmap
Edge AI on your own GPUs
High-performance on-prem AI for sovereigndeployments
MCP + A2A architecture
An AI agent orchestration platform coordinating enterprise AI agents across your content pipeline, standards-based, not proprietary lock-in
What ioGallery Does
ioGallery is where your team sees the work of ioMoVo's AI. Every file across ioCloud and connected drives is indexed, tagged and searchable in one view, using the AI models you choose, on the infrastructure you choose.
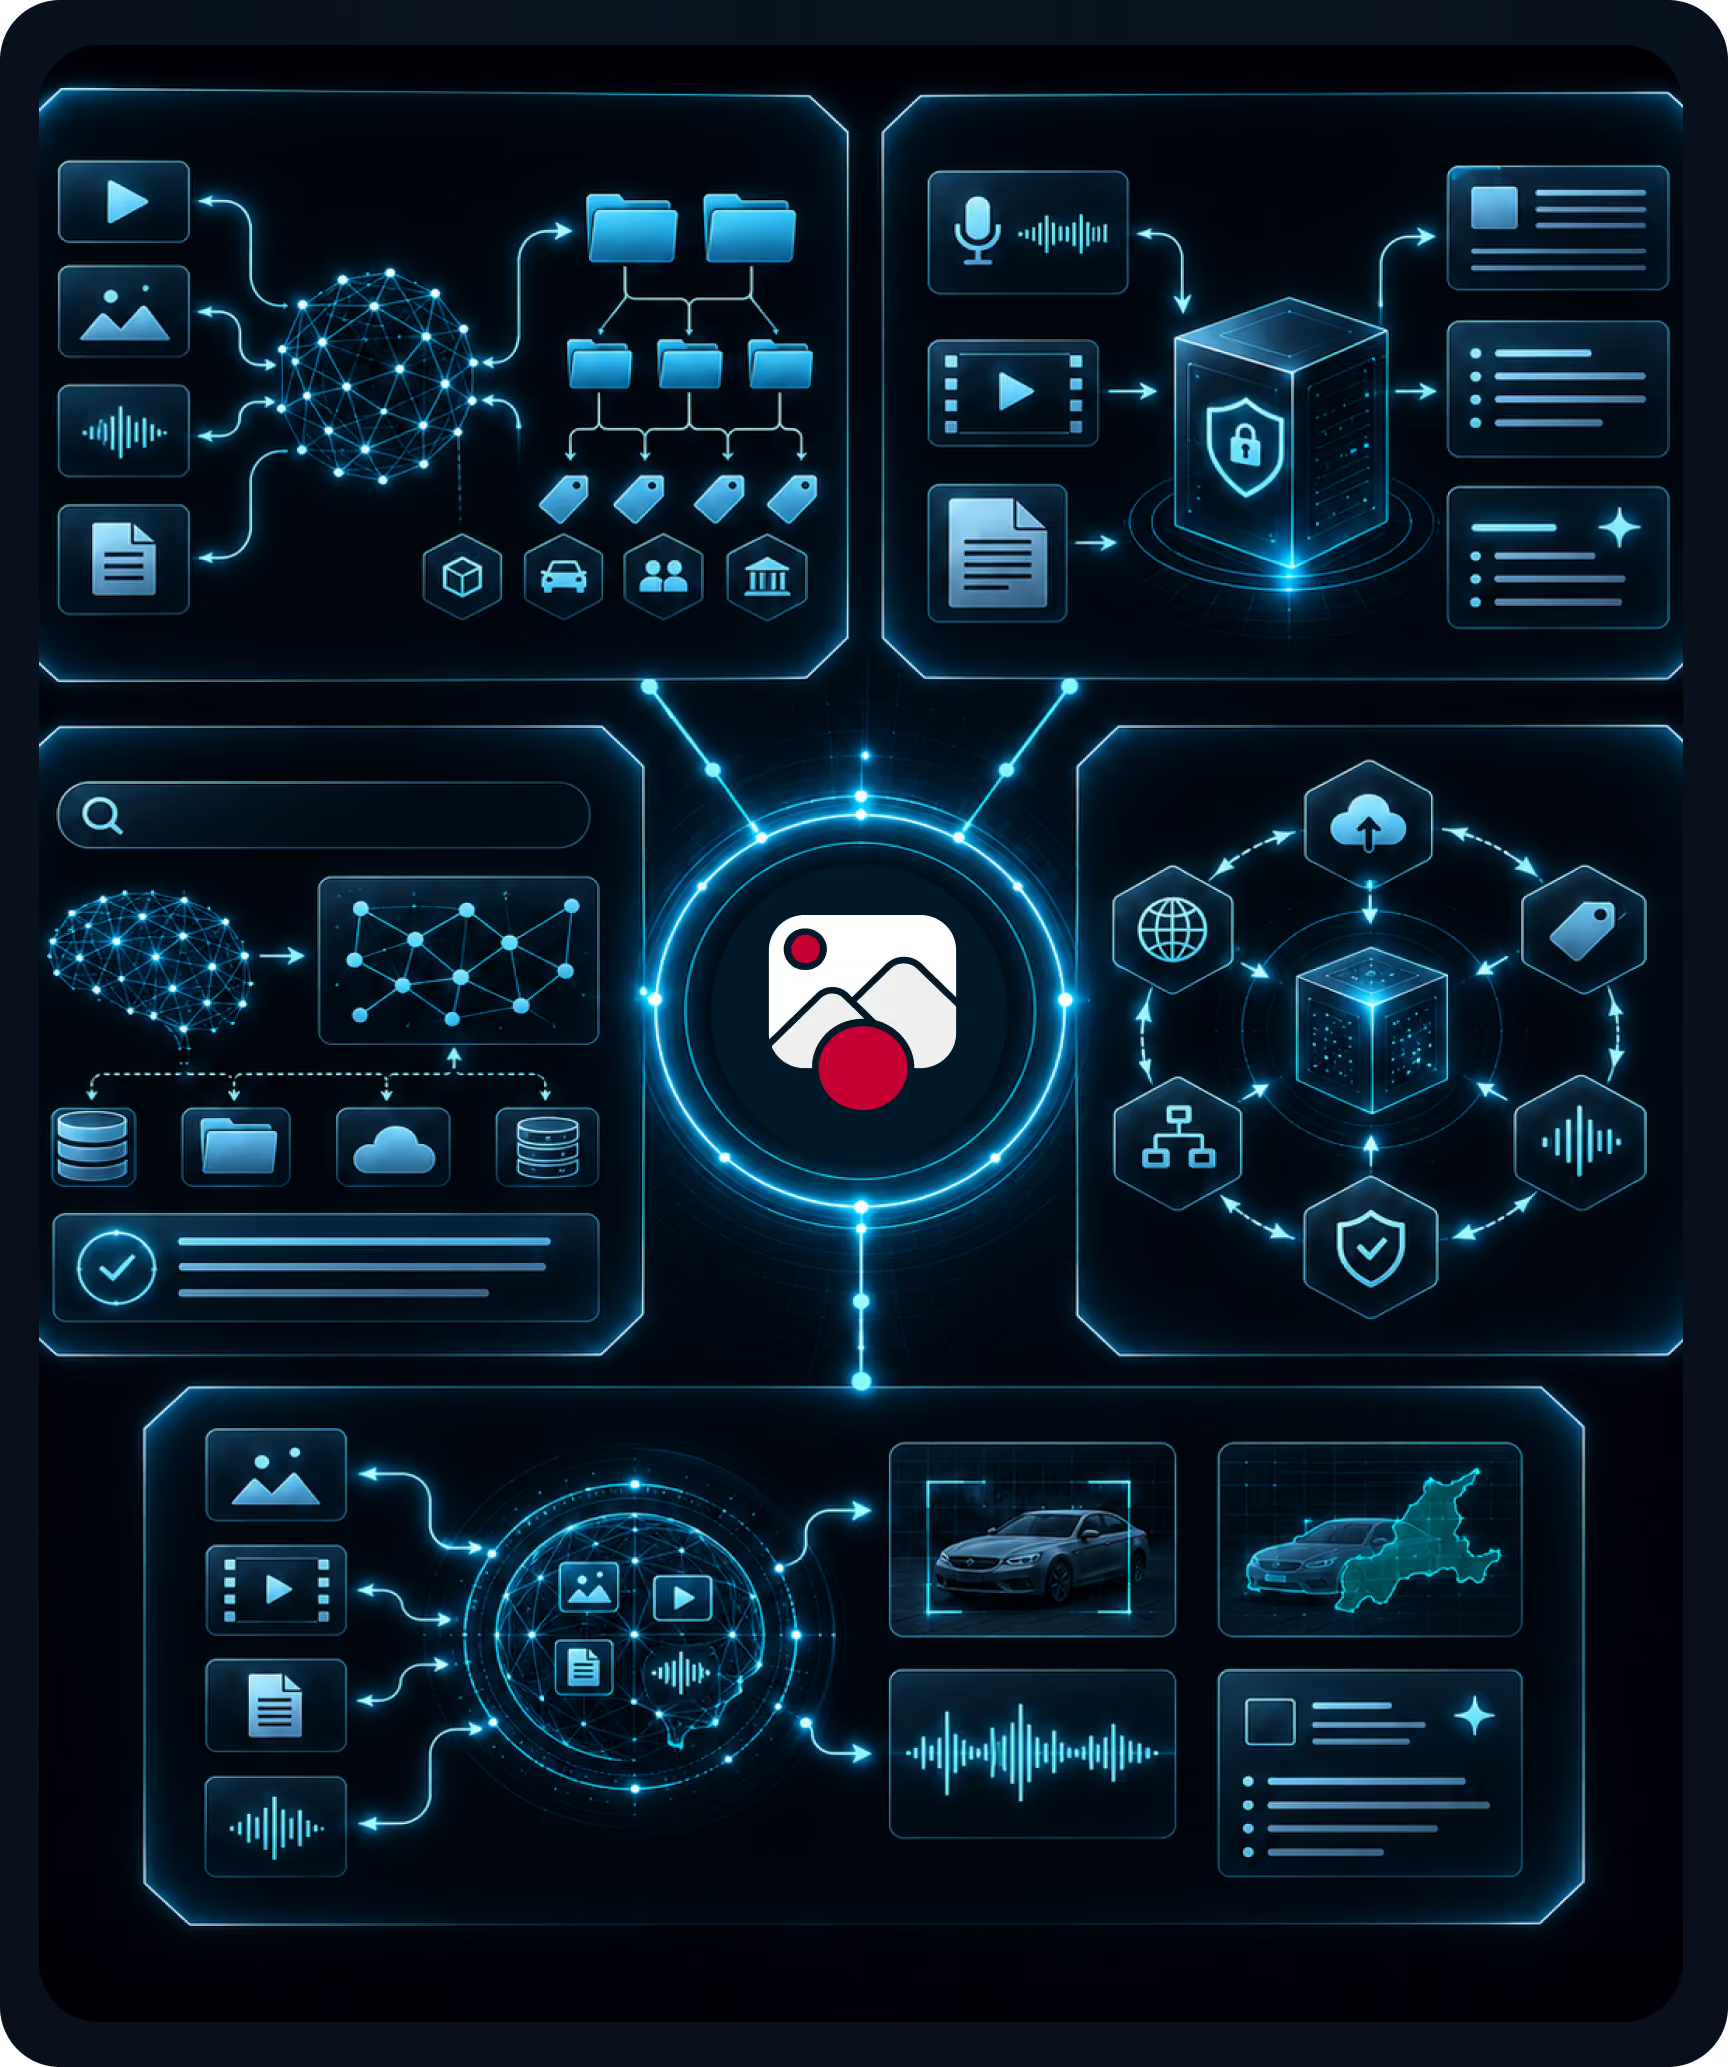
Auto-tagging and classification
Apply taxonomies and classifications across video, image, audio, and document content automatically. Custom taxonomies and fine-tuned classification models supported. Vertical-specific (medical, legal, brand, regulatory) classification through fine-tuned domain models.
Transcription, OCR, summarization
Automatic speech-to-text for audio and video using Whisper or other ASR models. OCR for scanned documents and image text. Summarization of long-form content using your chosen LLM. All processing respects your deployment’s data boundary - sovereign deployments keep transcription and summarization entirely on-prem.
Semantic search and RAG
Embedding-based semantic search across all ioCloud and ioHub-connected content. Retrieval-augmented generation grounds LLM responses in your actual content, not training data. RAG operates within your data boundary in sovereign deployments — no content leaves customer infrastructure for retrieval, embedding, or generation.
AI agents
Six specialized agents in ioMoVo’s A2A architecture coordinate to execute end-to-end content pipelines: ingestion (handles content arrival), metadata (auto-tagging and enrichment), transcription (speech-to-text and OCR), compliance (sensitive-data scanning and policy enforcement), workflow (ioFlow approval coordination), and portal publishing (ioPortal delivery).
Multimodal RAG and vision
Vision and multimodal model support — YOLO for object detection, BioCLIP for vision-language understanding, Segment Anything for image segmentation, custom VLMs for domain-specific use cases. Multimodal RAG combines text, image, video, and metadata in unified retrieval.
BYO-AI: Bring Your Own Model Architecture
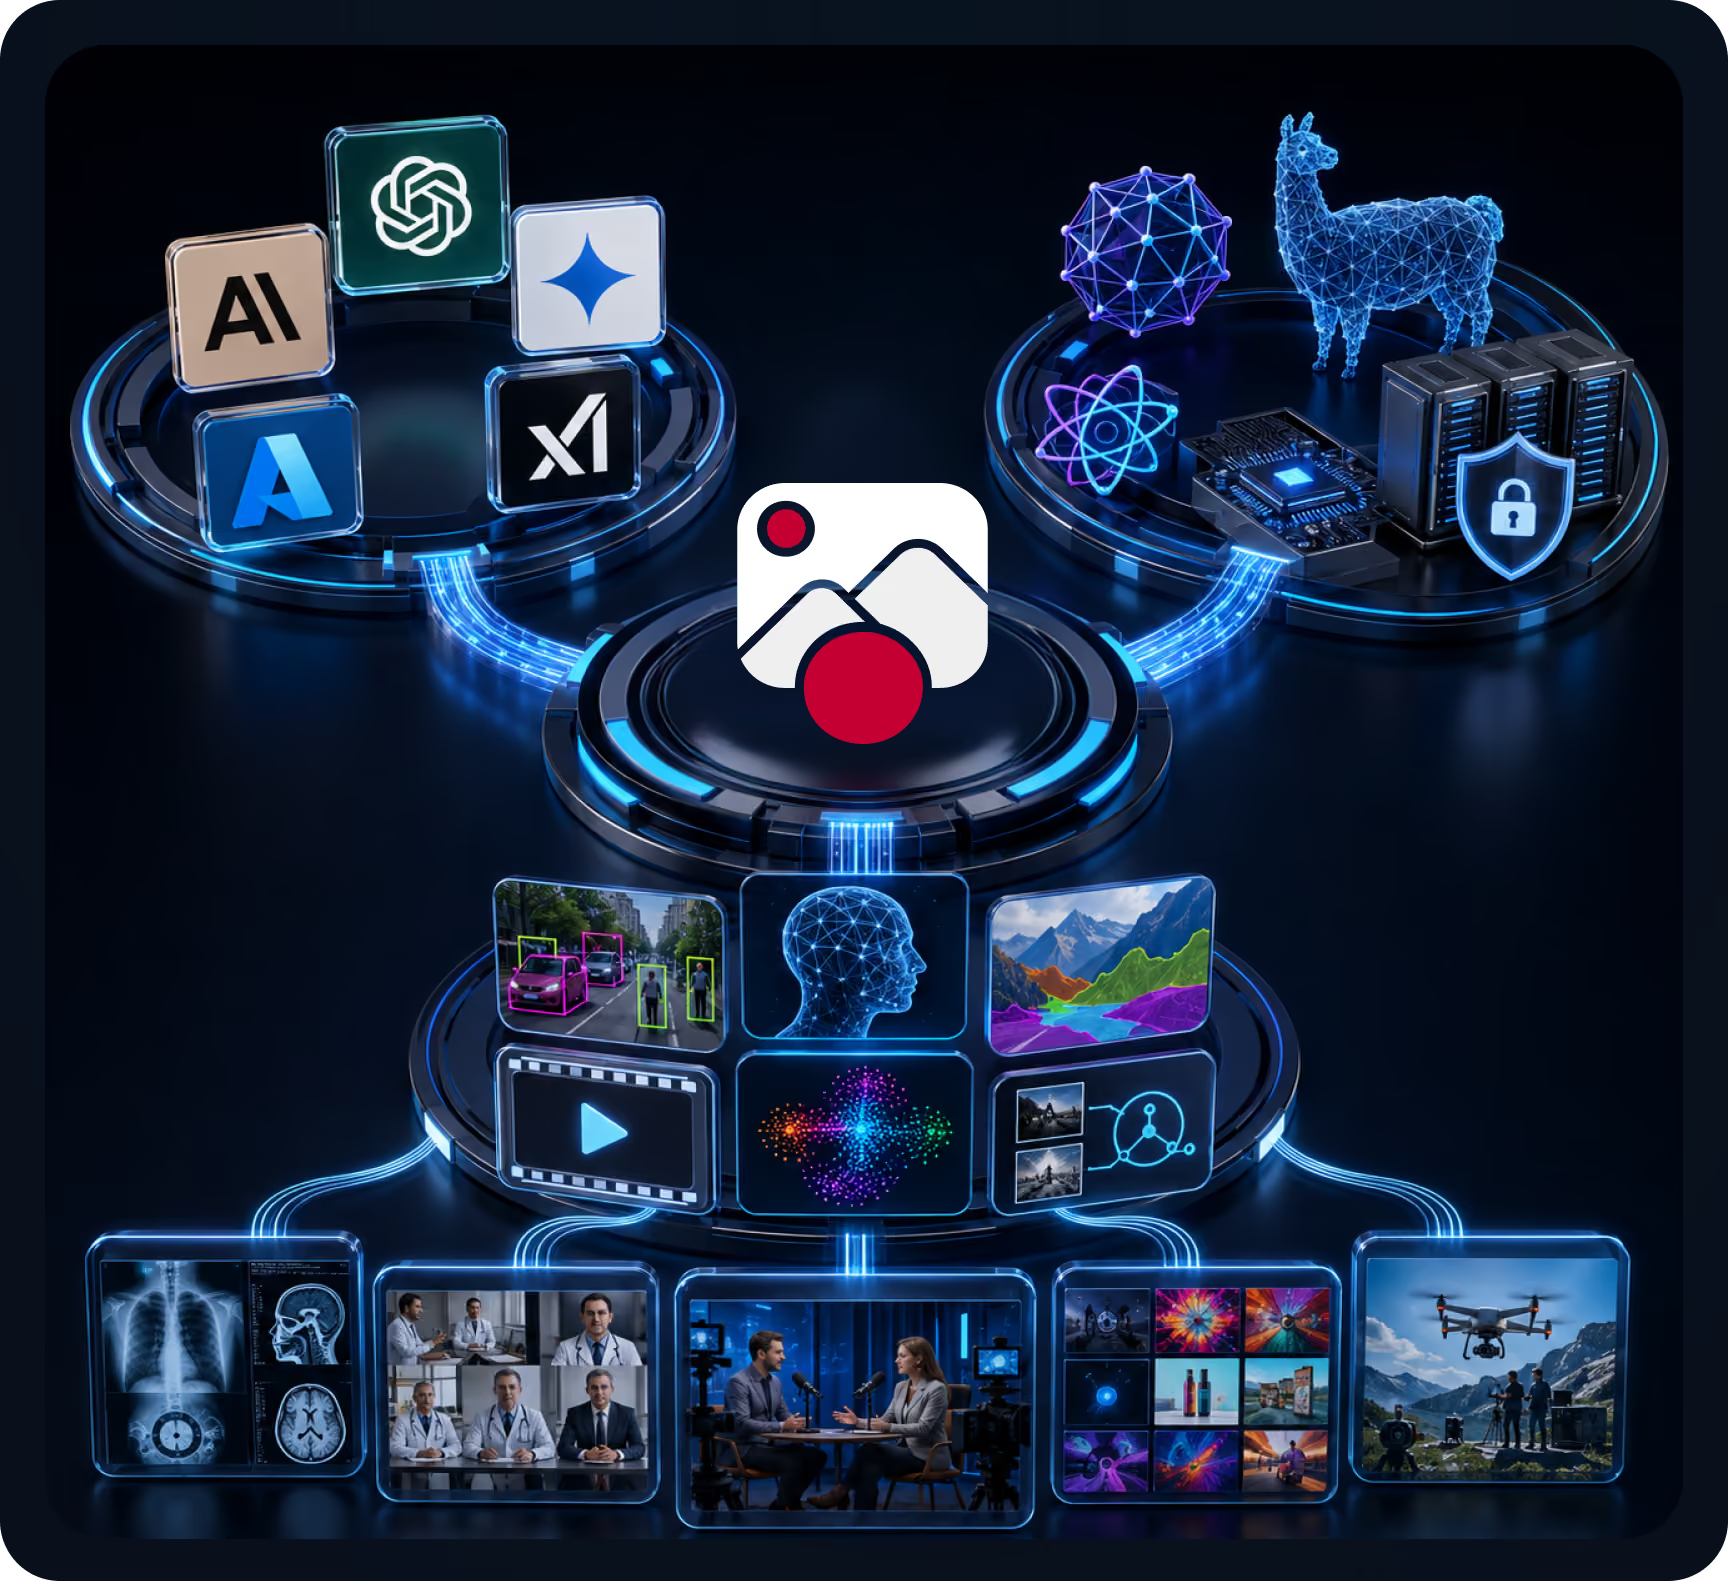
ioMoVo is model agnostic. Deploy ioMoVo's AI on the infrastructure that fits your compliance posture, your data sensitivity and your existing cloud relationships.

Commercial LLM providers
OpenAI (ChatGPT / GPT models), Anthropic (Claude), Google (Gemini / Vertex AI), Microsoft Azure OpenAI, XAI (Grok). Use trusted, production-grade LLMs through your existing cloud ecosystem.
Open-source LLMs
Open-source LLMs: LLaMA (Meta), plus open-source fine-tuned domain models. Deploy on your infrastructure for cost control, data sovereignty, or regulatory reasons.
Vision and multimodal models
Vision and multimodal models: YOLO (object detection), BioCLIP (vision language), Segment Anything (Meta) and custom VLMs. Multimodal RAG and VLM support is a current capability: ioMoVo's AI applies these to medical imaging, advisory board video, KOL recordings, brand assets and other visual content.
Edge AI deployment on your GPUs
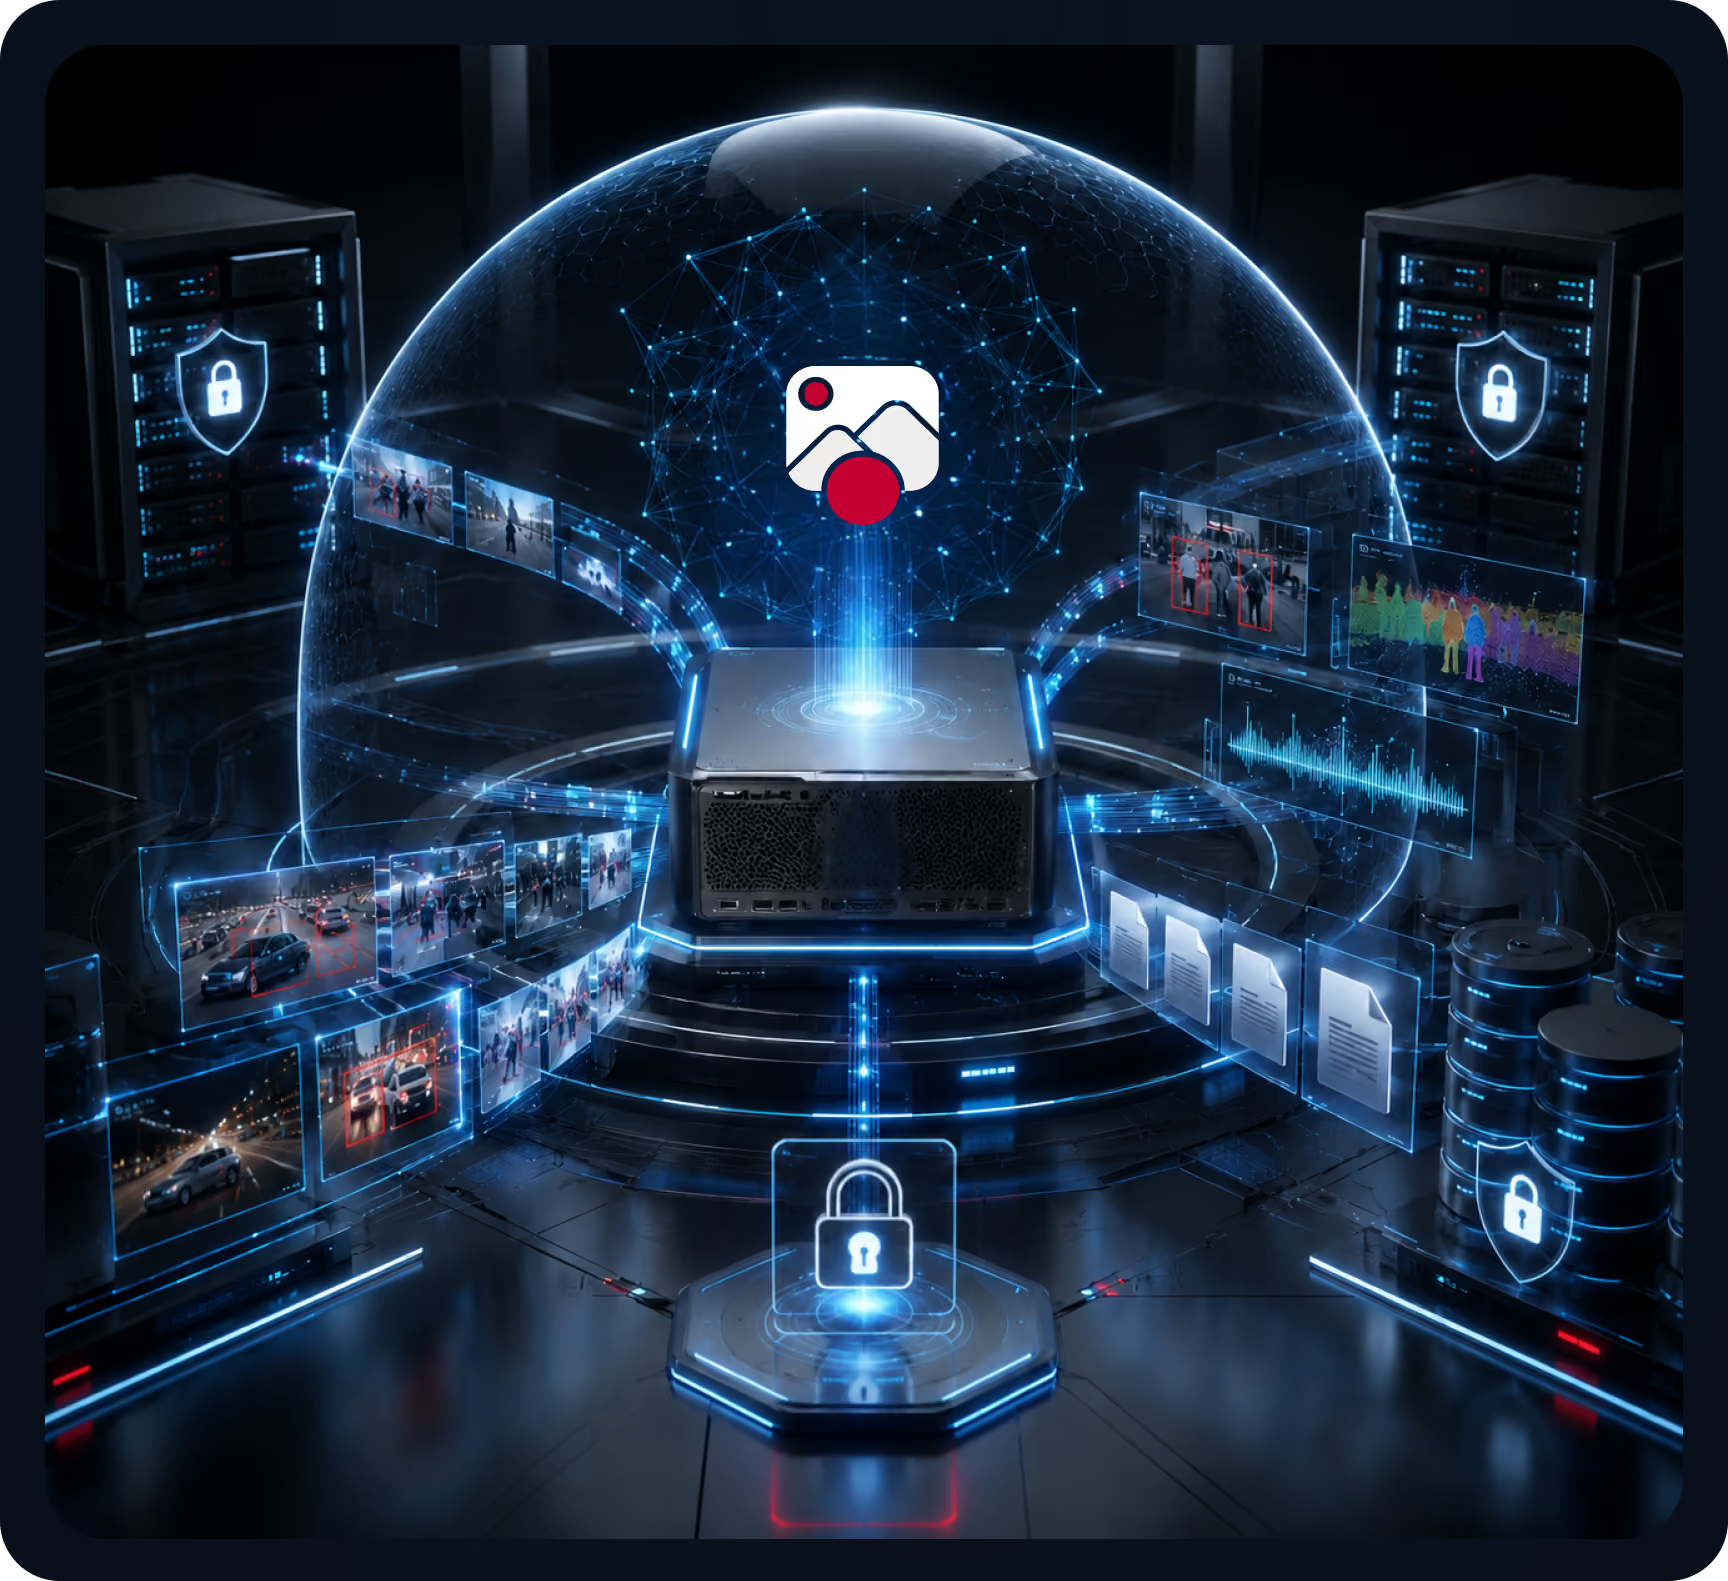
ioMoVo deploys and orchestrates open source AI models on your own GPU infrastructure for high performance, on premise AI processing. Run LLMs (LLaMA, fine tuned models) and vision models (YOLO, BioCLIP, Segment Anything) locally. Process video and images at the edge. Keep data fully on premise or air gapped, with no cloud roundtrip, and low latency inference for real time content workflows.
Sovereign / private AI deployment
On-prem LLM deployment, air-gapped environments, region-specific sovereign models (KSA / Saudi Arabia for MENA-region; others on request), and fine-tuned enterprise models trained on your proprietary content.
RAG-controlled boundary
In sovereign deployments, LLMs operate only within your data boundary. Content never leaves the customer-controlled infrastructure — not for inference, not for training, not for any platform telemetry.
MCP and A2A Architecture
MCP — Model Context Protocol
ioMoVo’s MCP-enabled architecture connects AI models to tools and data through the open Model Context Protocol. LLMsand open-source models can securely access ioCloud assets, ioHub-connected repositories, metadata, search indexes, ioFlow workflows, and external systems. Standards-aligned vs. proprietary integration: customers using Claude (which uses MCP natively) or other MCP-compatible LLMs plug into ioMoVo through their existing MCP setups. Future-proof for the agentic AI ecosystem where MCP is becoming the standard protocol.
A2A — Agent-to-Agent Architecture
Six specialized agents coordinate to execute end-to-end content pipelines without human handoffs at every step:
Ingestion agent
Handles content arriving from any source (ioHub repositories, Capture Layer, direct upload, API ingest). Triages content type and applies initial routing.
Metadata agent
Generates and enriches metadata. Auto tagging, classification, taxonomy mapping and custom field population.
Transcription agent
Handles speech-to-text and OCR. Applies summarization and key-moment detection.
Compliance agent
Scans for sensitive data (PII, PHI, regulated content). Applies governance policies. Flags compliance issues for human review.
Workflow agent
Coordinates with ioFlow to route content through approval cycles. Triggers next steps based on review outcomes.
Portal publishing agent
Handles delivery to ioPortal once approved. Applies brand templates, manages access permissions, tracks engagement.
Built for Enterprise AI on Real Content
What we hear from teams trying to apply AI to enterprise content:
Vendor-locked AI tools force content into specific clouds; IP-sensitive and regulated organizations can’t use them
AI features advertised as “integrated” are point solutions that don’t coordinate across content lifecycle
Hosted LLMs send content out of the customer environment — violates compliance posture for pharma, healthcare, financial services, public sector
On premise GPUs sit underused because content management software doesn't orchestrate them
Agentic AI vendors deliver demos but don’t coordinate multiple agents safely across enterprise content
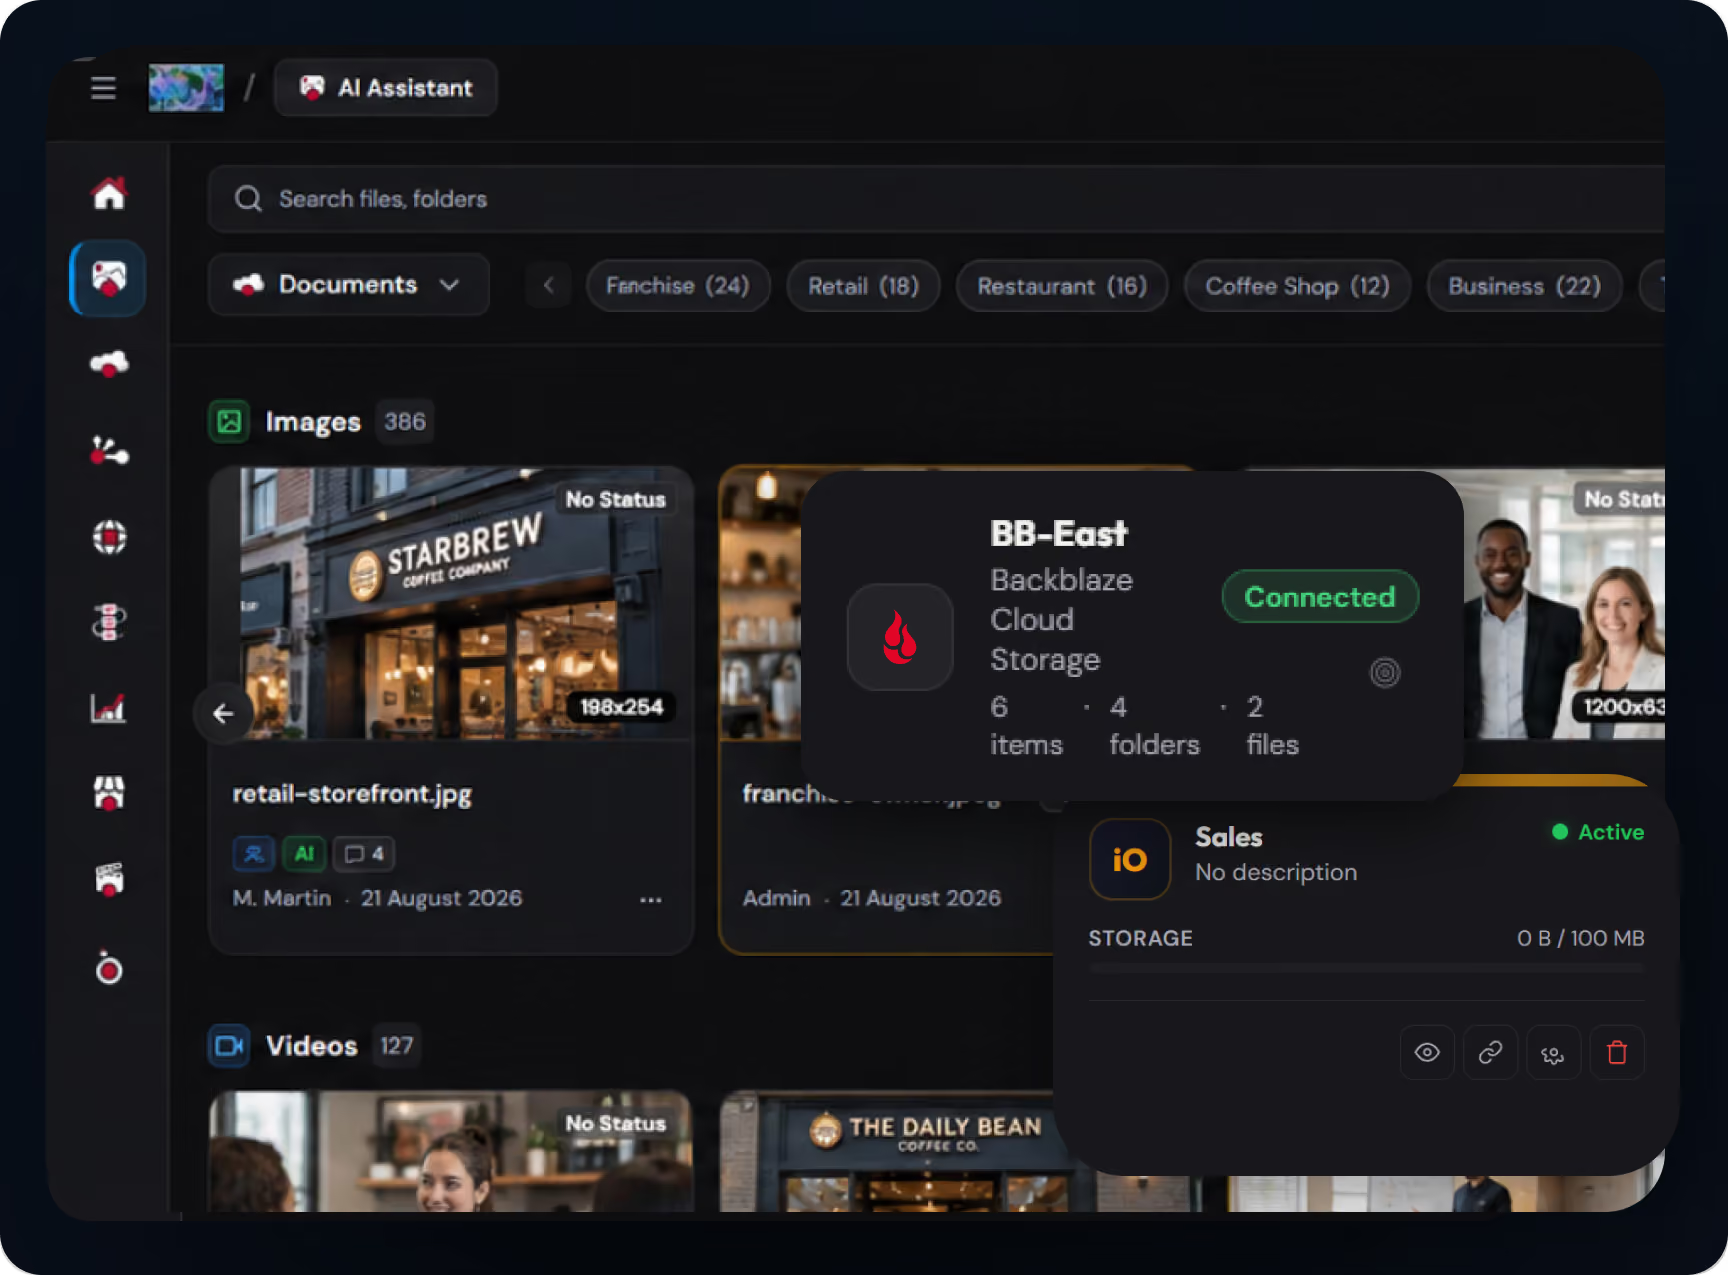
How ioMoVo solves it:
BYO-AI architecture — commercial, open-source, vision/multimodal, or sovereign. Customer chooses the model and infrastructure.
AI orchestration coordinates auto-tagging, transcription, semantic search, RAG, and agentic workflows across the same content layer (ioCloud).
Sovereign deployments operate within RAG-controlled boundary — content stays on-prem for inference, training, telemetry. KSA / MENA sovereign currently supported.
On premise GPU deployment: ioMoVo orchestrates open source models on your own GPU infrastructure, so the hardware you already own gets put to work.
A2A architecture — 6 specialized agents coordinate end-to-end content pipelines with audit trails on every action. Real agentic AI, not vapor.
Where Customers Use ioGallery
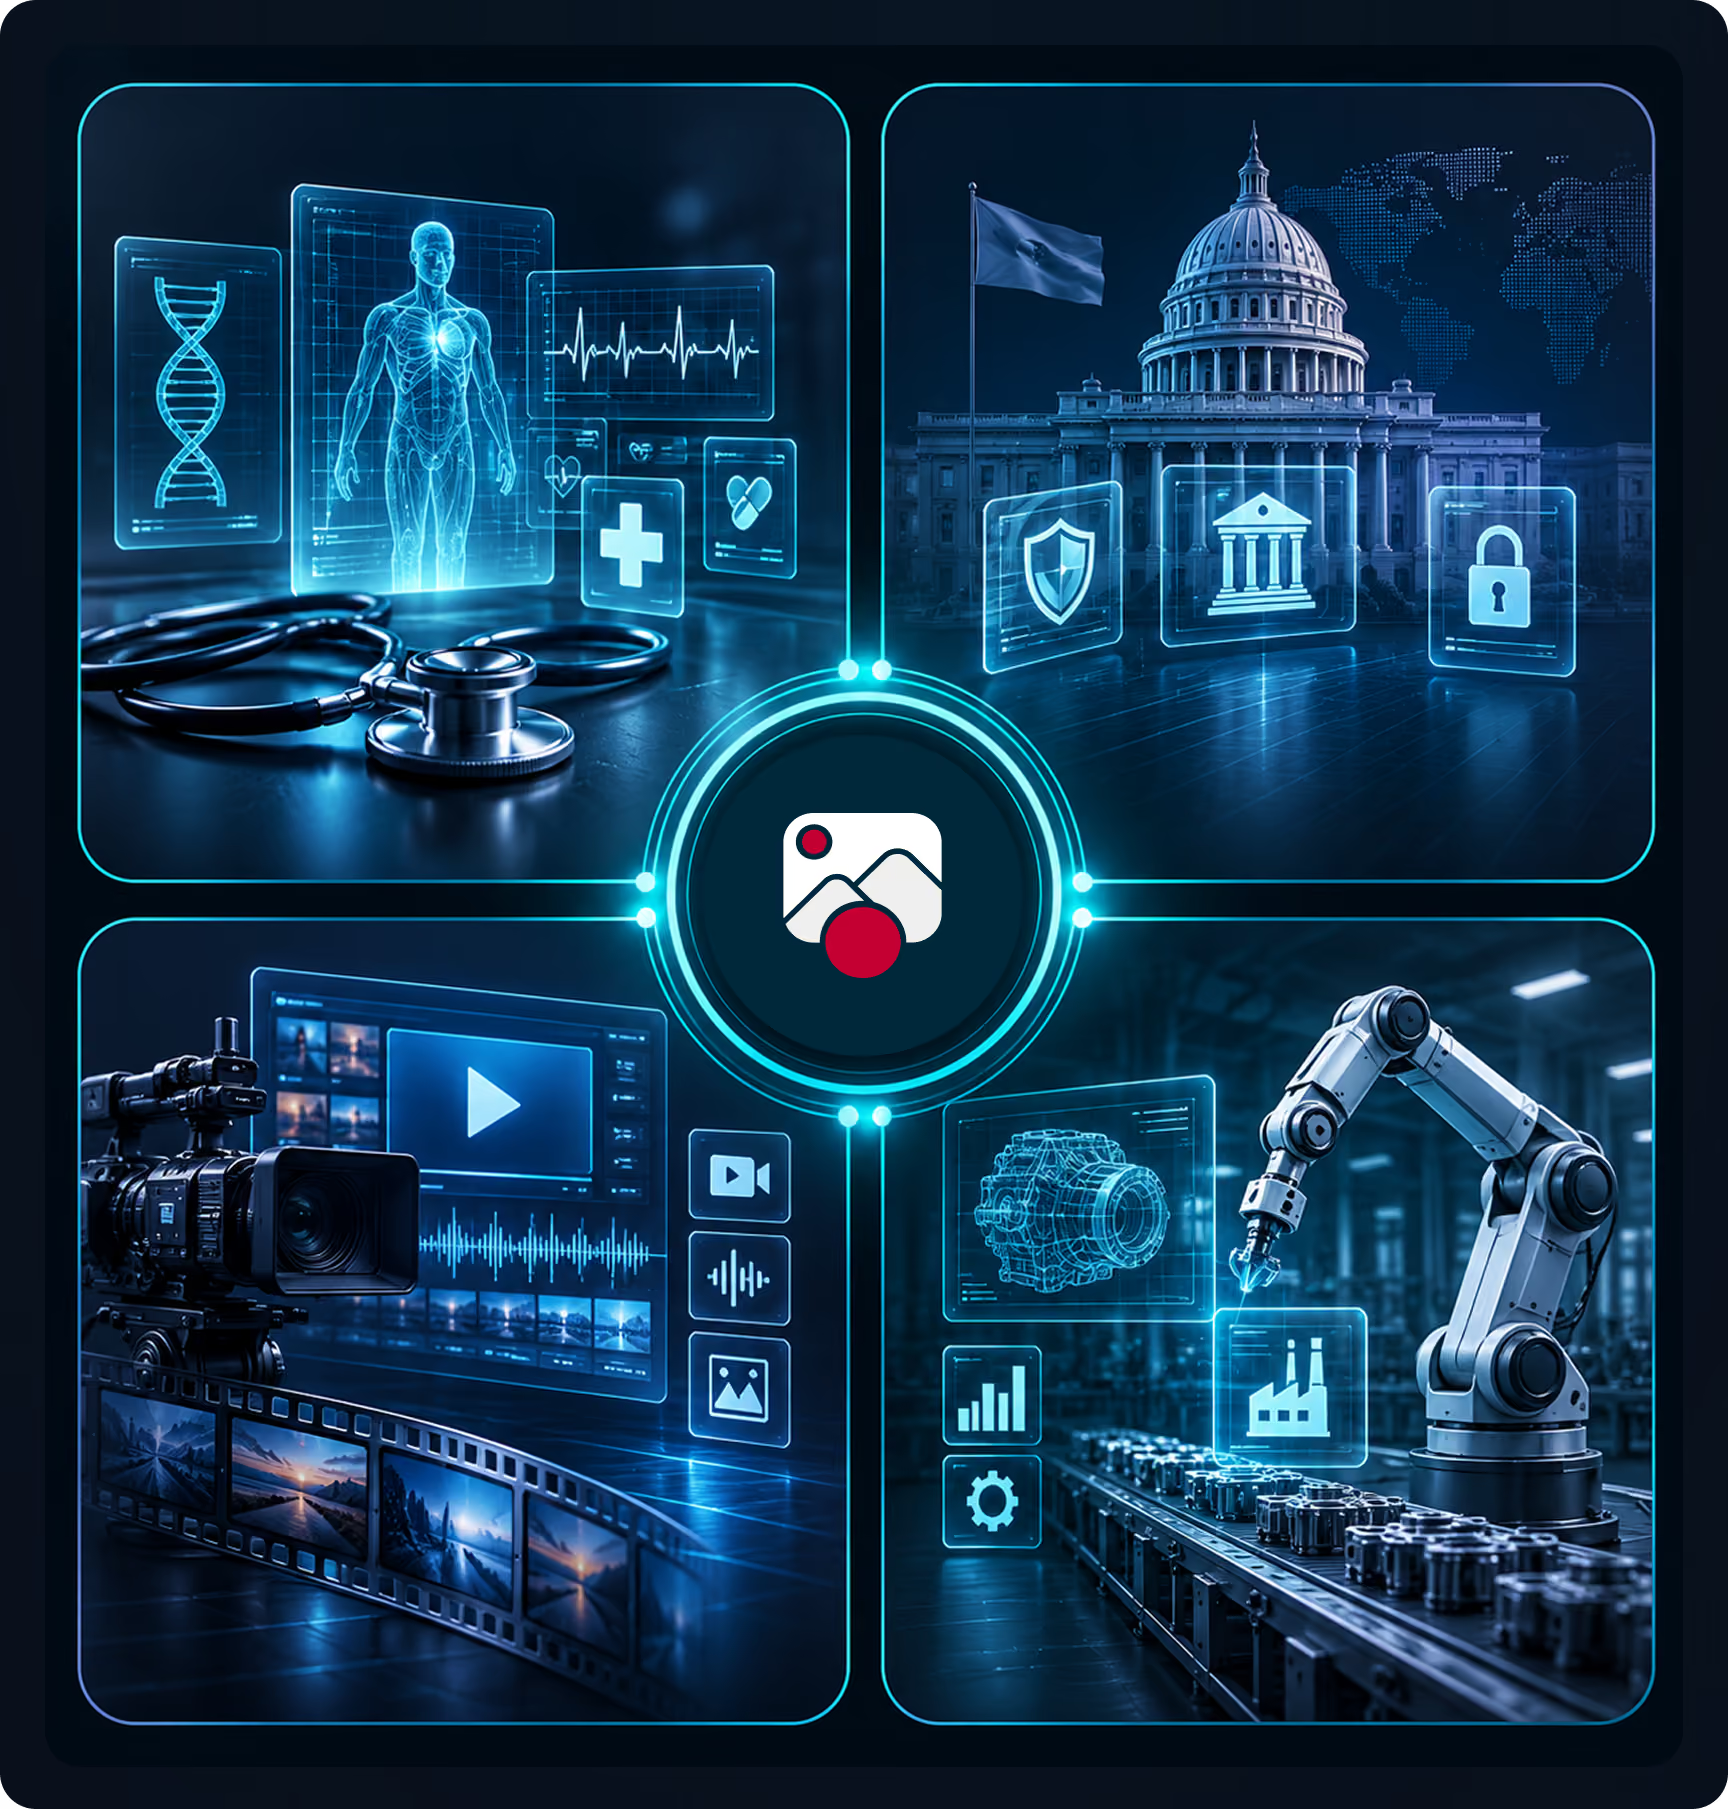
Pharma, healthcare, regulated industries
Sovereign LLM deployments for IP and PHI sensitivity. Fine-tuned medical terminology models. Compliance agent for sensitive-data scanning. RAG-controlled boundary keeps content on-prem, with every enterprise AI agent action logged for compliance review.
Government and public sector
Air-gapped deployments for classified environments. KSA / MENA sovereign for international government deployments. FedRAMP-aligned configurations.
Media and broadcast
Vision and ASR at scale for editorial tagging, transcription and content classification. Multimodal pipelines combining video, audio and metadata. On premise GPUs for high volume video processing economics.
Manufacturing and engineering
Vision models (YOLO + custom VLMs) for defect detection on factory imagery. Fine-tuned models for industry-specific taxonomies. On-prem for IP-sensitive engineering content.
Where ioGallery Fits in the ioMoVo Platform
ioMoVo is a cloud-native AI content platform with six modules and a capture layer. Each addresses a specific layer
of the content lifecycle.
Frequently Asked Questions

ioMoVo is model agnostic. Commercial LLMs (OpenAI, Anthropic, Google Gemini and Vertex AI, Microsoft Azure OpenAI, xAI), open source LLMs (LLaMA), vision and multimodal models (YOLO, BioCLIP, Segment Anything, custom VLMs), audio models (Whisper and other ASR) and fine tuned enterprise models trained on customer content. Bring your own keys and your own infrastructure. Every AI agent in the pipeline respects your chosen model and data boundary.

Yes. ioMoVo deploys and orchestrates open source AI models directly on your own GPU infrastructure for high performance, on premise AI processing. ioMoVo orchestrates between cloud models (commercial LLMs) and on premise models, including LLMs (LLaMA, fine tuned), vision (YOLO, BioCLIP, Segment Anything), audio (Whisper) and multimodal pipelines.
MCP (Model Context Protocol) is the open standard for connecting LLMs to tools and data. ioMoVo’s MCP-enabled architecture lets your LLMs (Claude, OpenAI, open-source) securely access ioCloud assets, ioHub-connected repositories, metadata, search indexes, and ioFlow workflows through MCP — standards-based, not proprietary integration. Future-proof for the agentic AI ecosystem.
A2A (Agent-to-Agent) architecture lets specialized agents coordinate to execute content pipelines without human handoff at every step. ioMoVo includes 6 specialized agents built as AI agents for enterprise content pipelines: ingestion, metadata, transcription, compliance, workflow, and portal publishing. Each agent has audit logging on its actions. Humans stay in the loop for high-stakes decisions (compliance flagging, workflow approvals).
In sovereign deployments, LLMs operate only within your data boundary — RAG-controlled, with no content leaving the customer-controlled infrastructure for inference, training, or platform telemetry. Region-specific sovereign deployments are supported including KSA / Saudi Arabia for MENA-region; other regional sovereign deployments supported on request.
See ioGallery on your AI infrastructure of choice
Book a 15 minute walkthrough. We'll show ioGallery and ioMoVo's AI running your chosen models (commercial, open source, sovereign or on premise GPUs) on content like yours, with MCP and A2A in action. No slides, no generic demo.